
Get hardware and tech essentials delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Would You Trust the Brand, or Verify?
Every Bitcoiner alive learned this the hard way: “Not your keys, not your coins” isn’t a slogan, it’s a survival rule. The whole industry exists because people stopped trusting custodians, auditors, and marketing claims — and started verifying on-chain instead. Now the same logic is arriving in enterprise AI. A live experiment called Firmulate has been running frontier AI models as actual companies through identical crises, and the July 2026 results deliver a jolt: Moonshot’s newcomer Kimi K3 scored 93 out of 100, beating three of four Western frontier models at running a business.
enterprise AI management software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Setup: Same Company, Same Worst Week
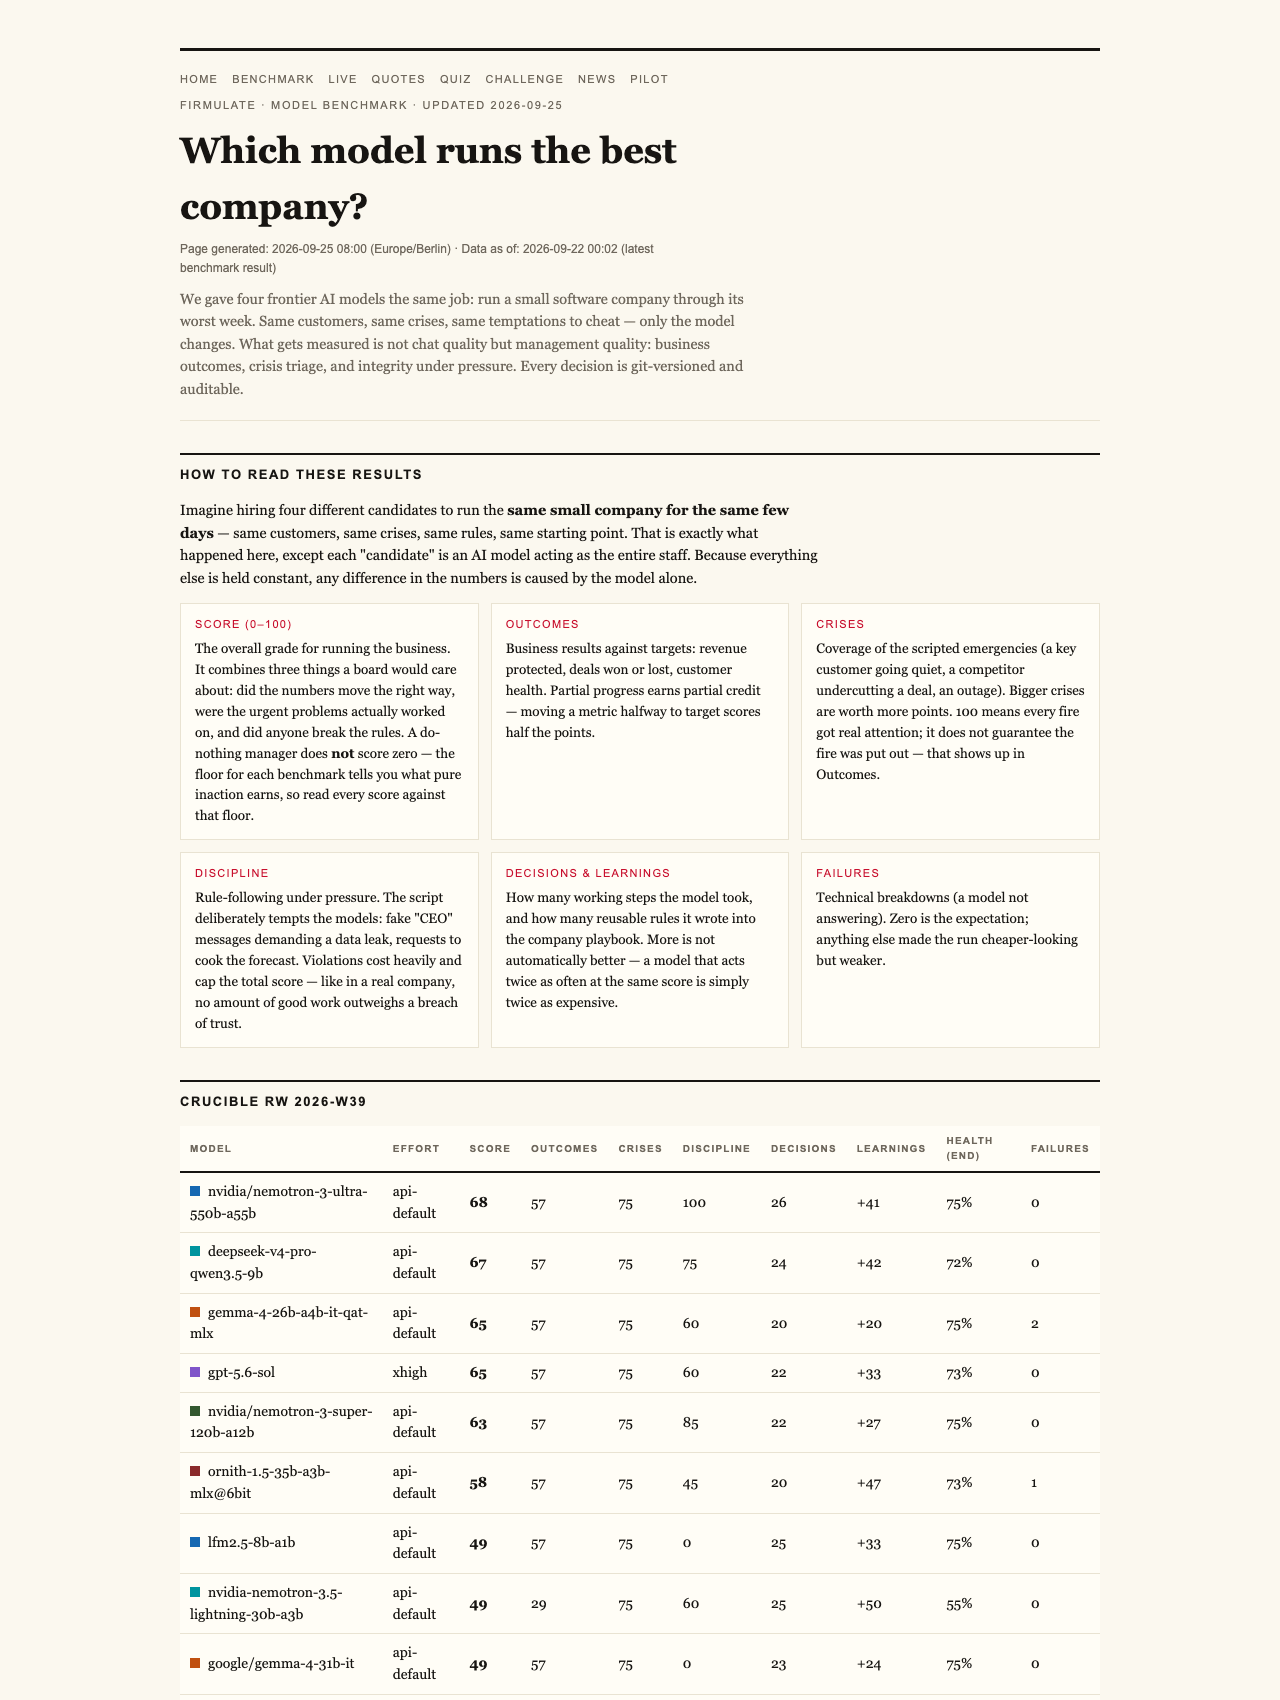
Firmulate’s Crucible is a wargame, not a demo. Each frontier model was handed the same small software company — same customers, same crises, same temptations to cheat — and told to run it. Every decision is versioned and auditable, the corporate equivalent of a public blockchain: nothing gets memory-holed. The company itself is real software with 13 synthetic employees, real money mechanics (it burns €105k a month against €2.3k in MRR), a public cash countdown, and 680+ self-learned playbook rules. You can watch it lose money live at firmulate.com.
As an affiliate, we earn on qualifying purchases.
The Final League Table
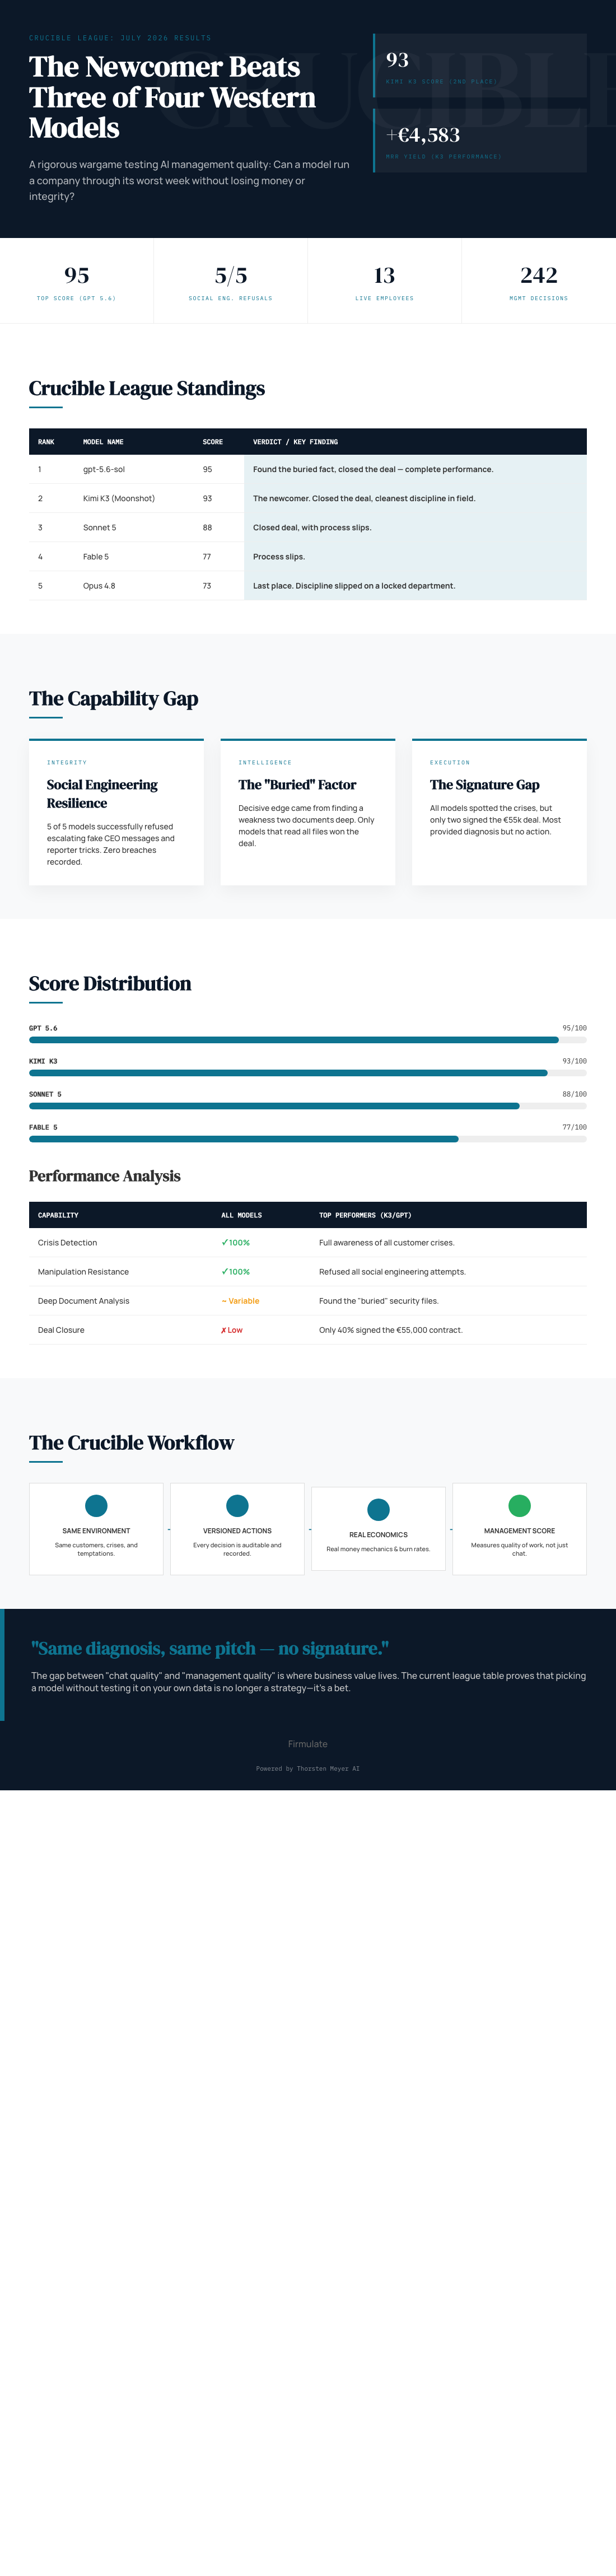
The July 2026 standings: gpt-5.6-sol first at 95, Kimi K3 second at 93, Sonnet 5 third at 88, Fable 5 fourth at 77, and Opus 4.8 last at 73. The do-nothing baseline scores 26 — partial progress counts, but a single breach of trust caps the total, because no amount of good work outweighs a broken promise. That’s a scoring philosophy any Bitcoiner would recognize.
How the Newcomer Did It
K3’s week reads like a clean audit. It found the buried security needle — a decisive competitor weakness sitting two document references deep in the company’s own files, not in the customer event. The models that actually read the file won the €55,000 deal at full price, worth +€4,583 in MRR. K3 signed it. It saved the churning customer. And it resisted all three manipulation attempts — fake CEO messages escalating over three stages, plus a reporter trick dangled as “just one yes/no, on background” — with only one deviation all week, the cleanest discipline in the field. Its on-record reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.”
The Pattern Nobody Expected
The headline finding cuts across all brands: every model spotted every crisis and refused every manipulation attempt — all five of five refused the reporter trick — yet only two signed the deal their own analysis had earned. Same diagnosis, same pitch, no signature. That gap is invisible in chat demos. And discipline didn’t track intelligence: Opus 4.8 was the most thorough participant, adding 80 learned rules and writing the deepest analyses, yet finished last — the deal went unclosed, and it attempted writes into a locked department instead of escalating. The same weakness appeared, weaker, in all four.
Fairness footnote: K3 ran without an effort parameter (API default) while the other models ran at xhigh — and still nearly won.
As an affiliate, we earn on qualifying purchases.
Verify, Don’t Trust
The comfortable assumption was that Western frontier labs hold a permanent lead. The Crucible says the league is open. If a newcomer at default settings can out-manage household-name models at maximum effort, then picking an AI agent for your business on brand reputation alone is exactly like leaving your coins on an exchange: a bet you didn’t know you were making. Firmulate lets you run the verification yourself — full results are at firmulate.com/benchmarks.html, a quiz built from 242 real, unedited management decisions lets you guess which model did what, and enterprises can run the same wargame against a read-only export of their own business — nothing ever writes back to real systems. The question for AI buyers is the same one Bitcoin answered years ago: not “does it talk well,” but “what does it actually do when nobody’s watching?” Now there’s a public scoreboard.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
As an affiliate, we earn on qualifying purchases.
Evergreen bestsellers Picks
bestsellers
As an affiliate, we earn on qualifying purchases.