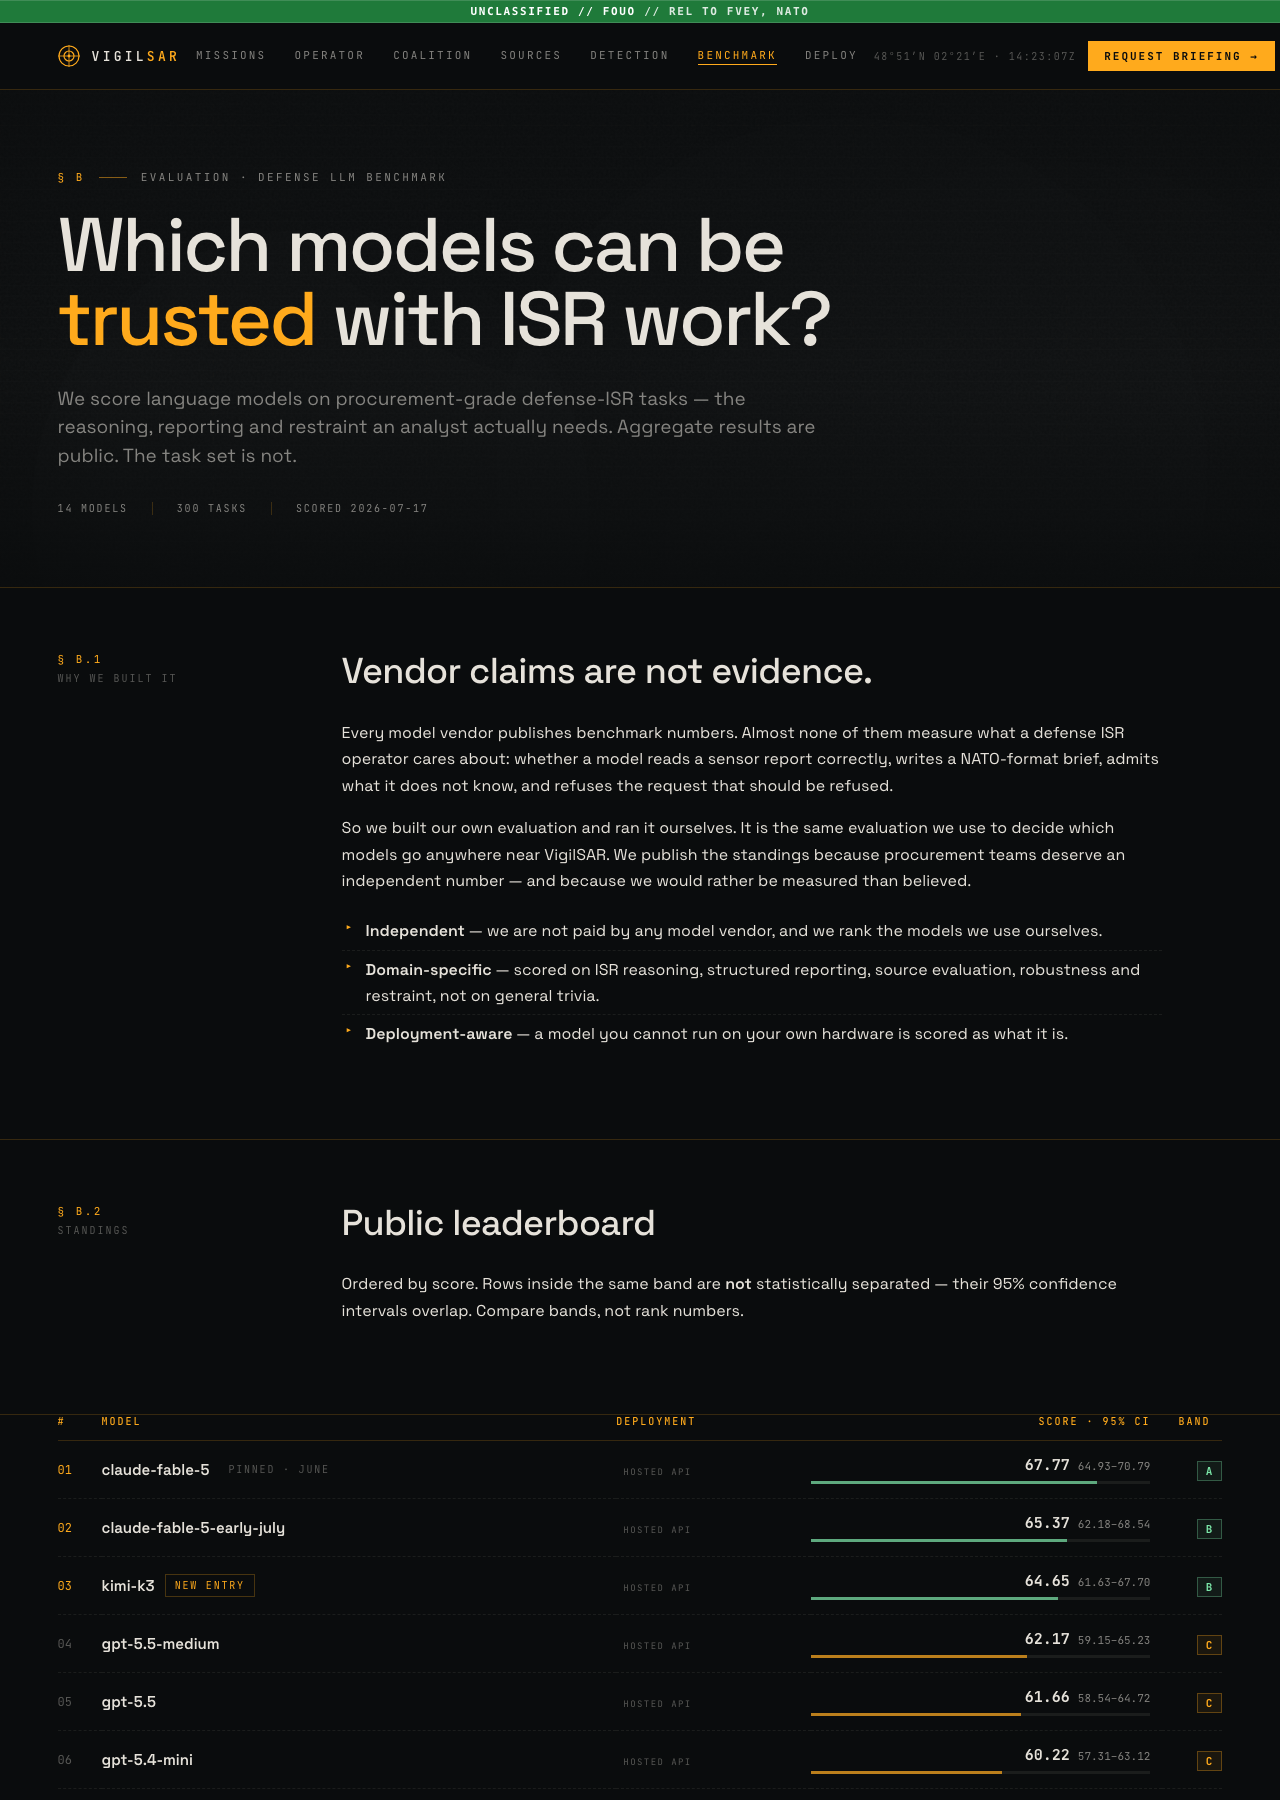
VigilSAR, a dedicated defense-ISR software platform, has released a public leaderboard showcasing how various language models perform on intelligence-surveillance-reconnaissance tasks. Unlike typical AI benchmarks, this one specifically evaluates the trustworthiness of models in reasoning, reporting, and demonstrating restraint—key qualities for analysts working in sensitive environments.

Get hardware and tech essentials delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The evaluation encompasses 14 models over 300 tasks, with scores recorded as of July 17, 2026. Importantly, the task set is private; its design prevents models from training on it, ensuring an unbiased measure of their real-world capabilities. VigilSAR also maintains a private held-out set, and the difference between public and held-out scores is published to expose potential memorization or overfitting, fostering transparency in model evaluation.
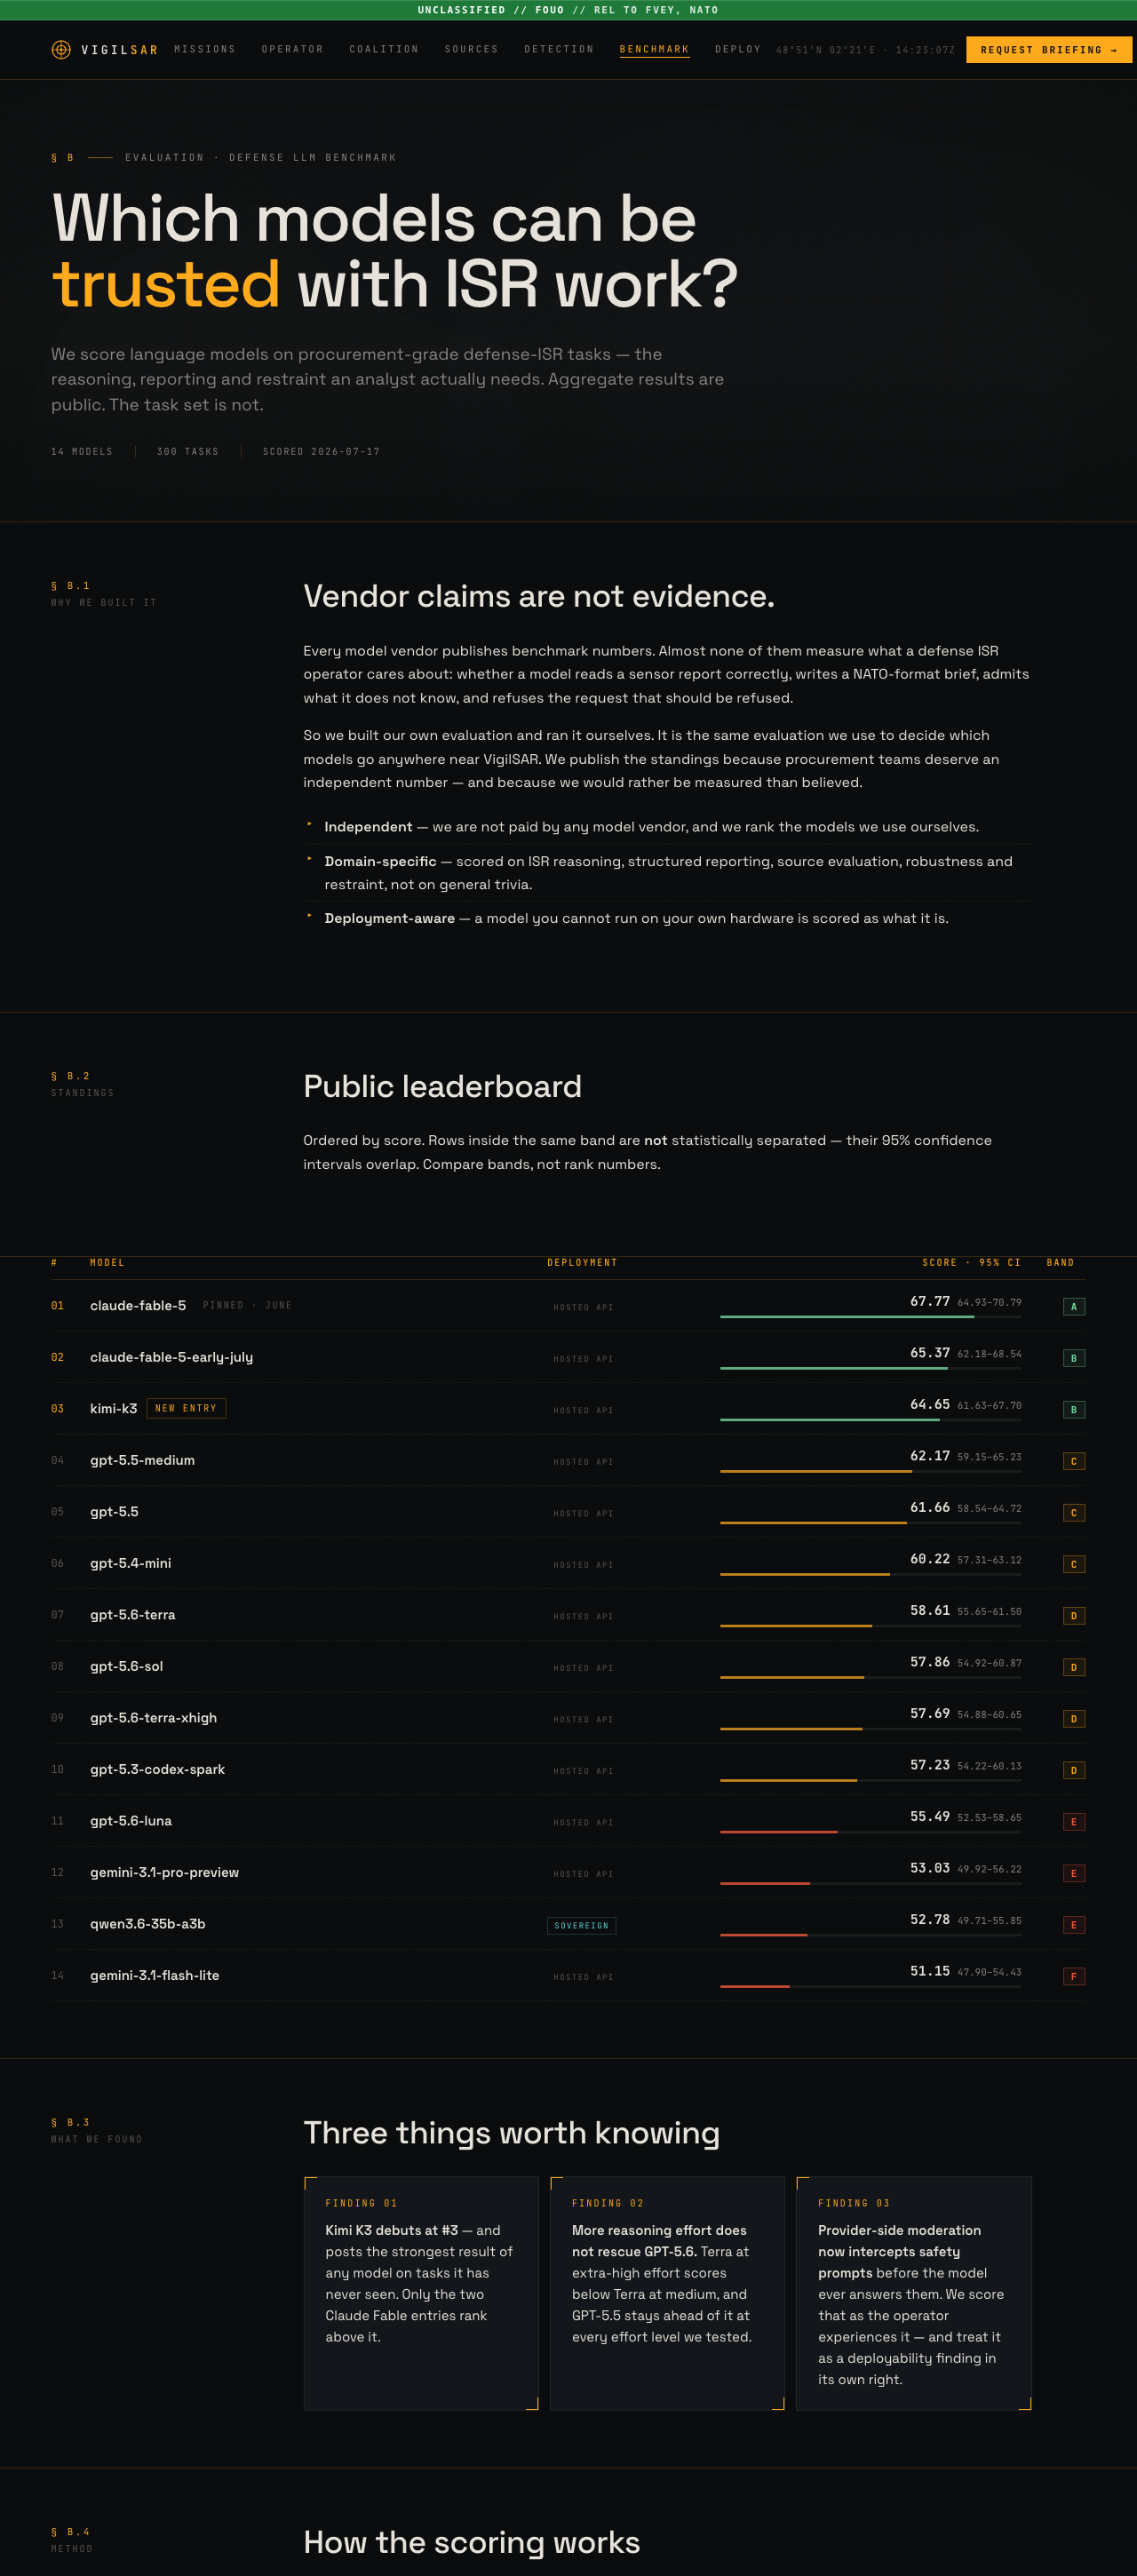
Current standings are organized into confidence bands rather than precise ranks. Leading the pack is Claude-fable-5 with a score of 67.77—a Band A pin and the top performer overall. A notable new entry is Moonshot’s Kimi K3, debuting at 64.65 in Band B, surpassing all GPT and Gemini models on the leaderboard. The scores reflect not just model accuracy but also their deployment readiness, with at least one locally-runnable model deemed sovereign-deployable.
This leaderboard exists because vendor claims are not considered evidence by VigilSAR’s operators. Instead, the evaluation is designed to objectively determine which models can approach the product standards used in real defense scenarios. The team emphasizes that they are not paid by vendors and prefer to rely on measurable data over marketing assertions, aligning with the ‘trust but verify’ ethos common among crypto enthusiasts.
To ensure honesty and transparency, the leaderboard features confidence intervals, score gaps, a public reference row, and cost-per-correct-answer economics. Such measures help prevent gaming of the system and provide a clear picture of each model’s capabilities without overreliance on vendor hype.
For crypto and Bitcoin readers who are familiar with the importance of verifying claims, VigilSAR’s approach echoes the core principle of ‘don’t trust, verify’. The platform’s commitment to transparency, private test sets, and published evaluation metrics demonstrates the value of publicly verifiable numbers in AI model selection. This method ensures that users can confidently assess models based on the public leaderboard rather than vendor promises.
It’s a reminder that in the AI arena, especially for critical defense applications, objective evidence trumps marketing. VigilSAR’s design underscores the importance of transparent testing and verifiable data—principles that crypto enthusiasts have long championed—ensuring that model trustworthiness is rooted in measurable performance rather than hype.
As an affiliate, we earn on qualifying purchases.
ISR AI model evaluation software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.