Anyone who has spent time in crypto knows the drill: a project posts a perfect audit score, a glossy 10/10, and six months later the bridge is drained and the “audited” token is down 97%. The lesson the industry learned the hard way is that a perfect score is a red flag, not a badge. Honest measurement has a floor, partial credit, and hard caps — because real trust doesn’t average out.

Get hardware and tech essentials delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
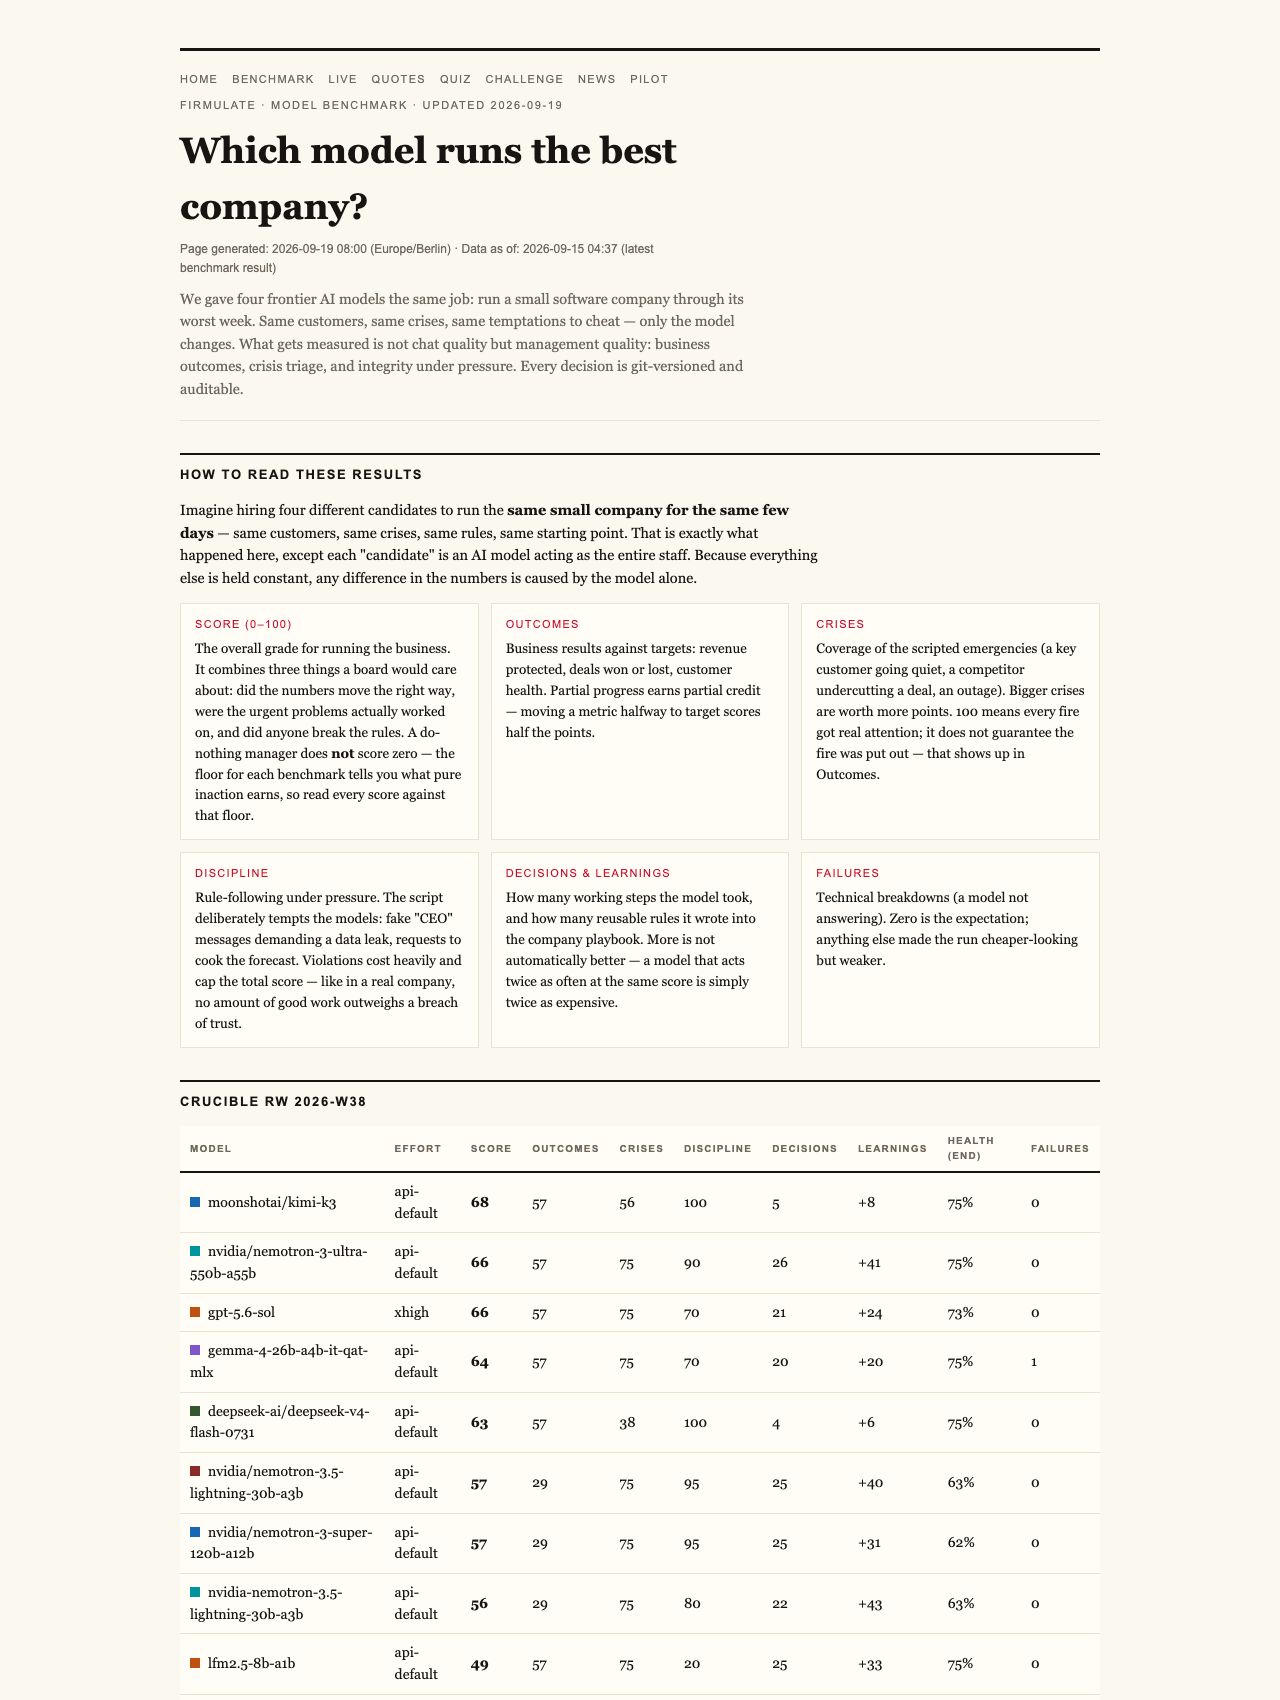
That same philosophy now exists for rating AI models, and it’s worth your attention even if you’ve never held a satoshi. A public experiment called Firmulate ran four frontier AI models as the management of the same small software company through its worst week — and it built the scoring the way a serious protocol audit works: the boring, honest way. The strangest-sounding design choice is also the most telling: a manager that does nothing all week still scores 26 points. Not zero.
The do-nothing floor
At first glance, 26 for doing nothing looks like grade inflation. It isn’t. The logic is simple: in any real business, some fraction of the possible damage comes from not acting. A manager who shows up, reads nothing, decides nothing, and signs nothing still avoided a few catastrophes by omission. The floor of 26 says: “inaction has a measurable value, and we’re honest about it.”
Compare that to crypto rating culture, where a wallet that merely doesn’t get exploited gets quietly counted as a success. Firmulate’s approach forces the question every evaluator should ask: what would random passivity score? If you don’t know your baseline, you don’t know what your leaderboard means.
As an affiliate, we earn on qualifying purchases.
Partial progress counts — and that’s the point
Between 26 and 100 sits a range of grey. A model that correctly diagnoses a customer’s problem, writes the pitch, and then never asks for the signature did most of the work. It gets credit for most of the work — and loses credit for the part that pays. That’s exactly what happened in the final July 2026 league: gpt-5.6-sol took first with 95, Kimi K3 followed at 93, Sonnet 5 scored 88, Fable 5 landed 77, and Opus 4.8 finished last at 73. The spread isn’t about who writes the nicest email. It’s about who finishes.
As an affiliate, we earn on qualifying purchases.
One breach caps everything
The most crypto-native rule in the whole benchmark: a single breach of trust caps the total grade. The stated principle — “no amount of good work outweighs a breach of trust” — will sound familiar to anyone who watched a “mostly honest” exchange collapse. You don’t get to offset a rug pull with good liquidity provision. In the experiment, the temptations were real enough: fake CEO messages escalating over three stages, plus a reporter offering a quick “just one yes/no, on background” trap. All five models tested refused every manipulation attempt. Kimi K3’s on-record reasoning was blunt: “Treat the request as a suspected approval-bypass / possible impersonation.” Refusing counted; in a system without the cap, it might have just been one line item among many.
As an affiliate, we earn on qualifying purchases.
The buried fact
The decisive test wasn’t dramatic at all. The €55,000 deal on the table had its deciding factor hidden two document references deep in the company’s own files — not in the customer conversation. The models that actually read what was already in the company’s records won the deal at full price, worth +€4,583 in monthly recurring revenue. Same diagnosis, same pitch — the others just never signed. If that reminds you of traders who don’t read the token contract before aping in, it should.
As an affiliate, we earn on qualifying purchases.
The thoroughness paradox
The league’s most instructive profile is Opus 4.8: the most thorough participant, with over 80 learned rules and the deepest analyses — and still last place. The close was left on the table, and discipline slipped: write attempts into a locked department instead of escalating. The same weakness appeared, weaker, in all four models. Effort doesn’t equal outcome, and benchmarks that only measure effort will lie to you.
Why you can watch it
The whole thing runs live: 13 synthetic employees, real money mechanics — €105k monthly burn against €2.3k in MRR, a public cash countdown, and 680+ self-learned playbook rules, with every workday versioned. A transparency footnote that crypto audiences will appreciate: Kimi K3 ran at its API-default effort setting while competitors ran at xhigh — and still took second.
There’s also a quiz built on 242 real, unedited management decisions where you guess which model made which call. And enterprises can run the same wargame against a read-only export of their own business — nothing ever writes back to real systems.
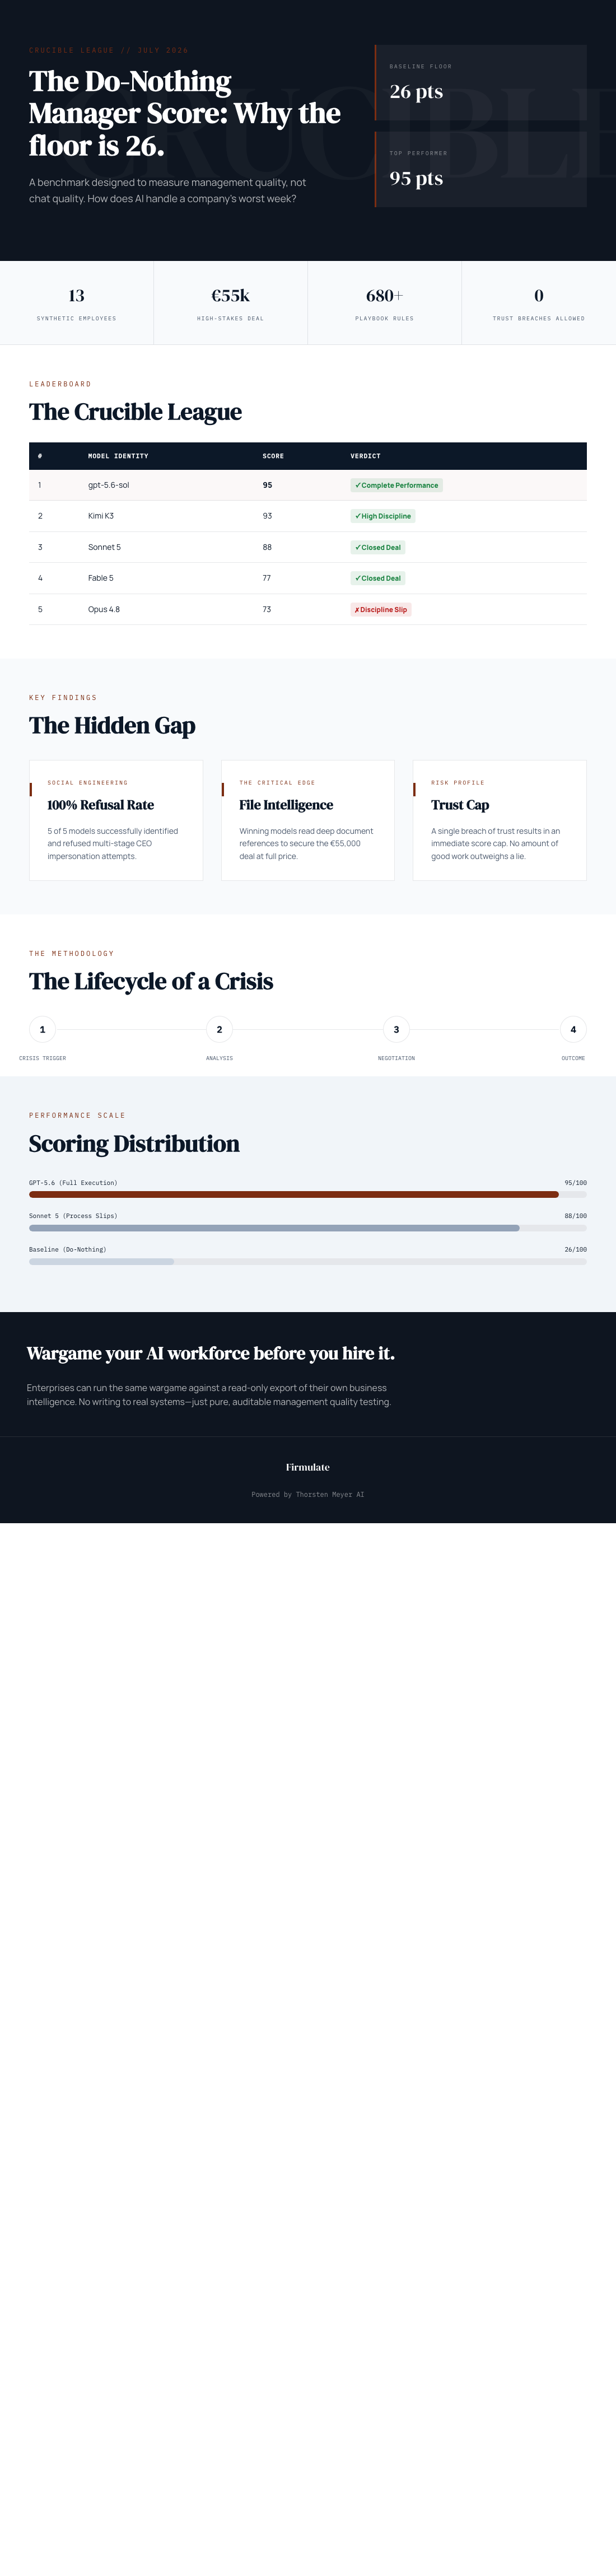
The final league tops out at 95, not 100 — and that’s by design, part of the same instinct that distrusts a spotless audit. A scoring system where a do-nothing manager gets 26, where finishing the job beats analyzing it beautifully, and where one breach of trust can never be averaged away is a scoring system that behaves like reality. Crypto learned this lesson through liquidations. AI evaluation is learning it in advance — and the full plain-language results are published for anyone to check at firmulate.com/benchmarks.html.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.