TL;DR
This article explores how to build robust, scalable end-to-end document pipelines for AI applications. It highlights key design principles, architecture choices, and operational practices confirmed by recent industry demonstrations.
This week, industry practitioners outlined a reference architecture for end-to-end document pipelines in AI, emphasizing simplicity, modularity, and operational safety. These developments confirm a shift toward pipelines that keep components decoupled, maintainable, and resilient, which is crucial as AI models and workflows become more complex and regulated.

Get hardware and tech essentials delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
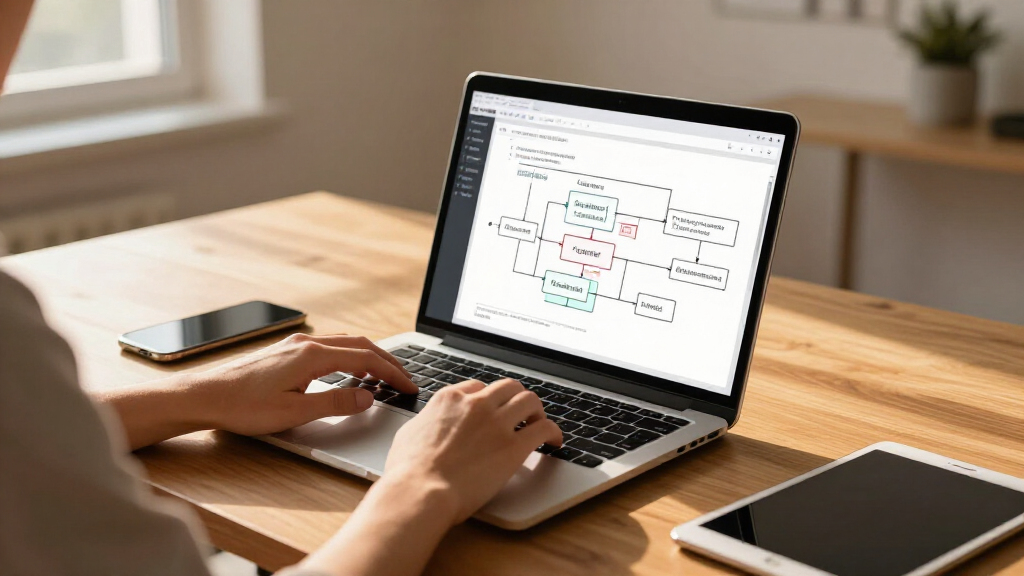
The core idea is that each pipeline component should be a narrow, single-purpose CLI, such as OCR or extraction models, invoked as subprocesses. This approach ensures easy swapping of models and reduces coupling between components, making pipelines more maintainable over time. The architecture relies on PostgreSQL as the central queue, utilizing simple transactional jobs with SKIP LOCKED for concurrency, crash safety, and idempotency based on content hashes.
Ingestion involves storing original bytes, computing hashes, and enqueuing jobs without complex processing. OCR models are designed to process page images into markdown, with model choices being routing decisions rather than ideological commitments. The extraction phase converts markdown into structured JSON, with separate passes for transcription and extraction, facilitating debugging and schema validation. Storage includes provenance data, enabling traceability and auditability, especially in regulated environments.
Recent demonstrations, such as Hugging Face’s showing of models running on local infrastructure and the AI Act’s transparency rules, reinforce the importance of operational control and local inference. These developments suggest a practical, scalable approach to deploying document pipelines that can adapt to model updates and regulatory requirements.
Operational Best Practices for Reliable Document Pipelines
Designing robust end-to-end pipelines is vital for organizations relying on AI for document processing, especially in regulated sectors. The architecture principles confirmed this week promote maintainability, safety, and flexibility, reducing operational risks and enabling easier model updates. This approach supports compliance with transparency rules and ensures data integrity, which are critical as AI adoption expands across industries.
Products Worth Considering

Ledger Nano Gen5 Crypto Wallet with Touchscreen, Black

Logitech MX Creative Console with 9 Customizable Keys, Graphite

Ledger Nano X Bluetooth Crypto Hardware Wallet
As an affiliate, we earn on qualifying purchases.
Recent Industry Movements in Document AI Architecture
Over the past week, industry leaders and practitioners have emphasized a reference architecture for document pipelines, driven by recent demonstrations of local inference, model swapping, and operational safety. The AI Act’s transparency requirements and the need for local inference have accelerated interest in architectures that keep data within organizational boundaries. These developments build on prior work showing that simple, modular components and transactional data management improve pipeline robustness and compliance.
“The pipeline should be a straightforward sequence of narrow CLI tools, each responsible for a single step, with the entire process managed via a central database.”
— Thorsten Meyer
Unresolved Questions About Pipeline Scalability and Flexibility
While the architecture principles are well-defined, it remains unclear how these pipelines will scale in extremely high-volume environments or integrate with more complex workflows involving multiple model versions and schema evolutions. Additionally, the long-term maintenance of prompt schemas and provenance data, especially in dynamic operational contexts, is still being explored.
Next Steps for Implementing and Evolving Document Pipelines
Organizations are expected to adopt these architecture principles in pilot projects, with ongoing refinement based on operational feedback. Future developments may include automation for model swapping, enhanced provenance management, and integration with compliance tools. Monitoring and benchmarking pipeline performance across different workloads will also shape best practices moving forward.
Key Questions
Why should I design my document pipeline with narrow CLI components?
Narrow CLI components promote modularity, making it easier to replace or update individual models without affecting the entire system. This approach simplifies maintenance and enhances flexibility.
How does using PostgreSQL as a queue improve pipeline reliability?
PostgreSQL provides transactional guarantees, crash safety, and concurrency control through SKIP LOCKED, ensuring jobs are claimed and completed reliably without complex external queue systems.
What are the benefits of separating transcription and extraction passes?
Separating these steps allows targeted debugging, schema validation, and schema evolution, making the pipeline more transparent and easier to maintain.
What challenges remain in implementing these pipeline principles at scale?
Scaling to high-volume environments, managing schema updates, and maintaining provenance data over time are ongoing challenges that require further operational refinement.
Will these principles apply to all types of document AI workflows?
While these principles are broadly applicable, workflows involving highly complex or specialized processing may require additional customization beyond the core architecture.
Source: ThorstenMeyerAI.com